
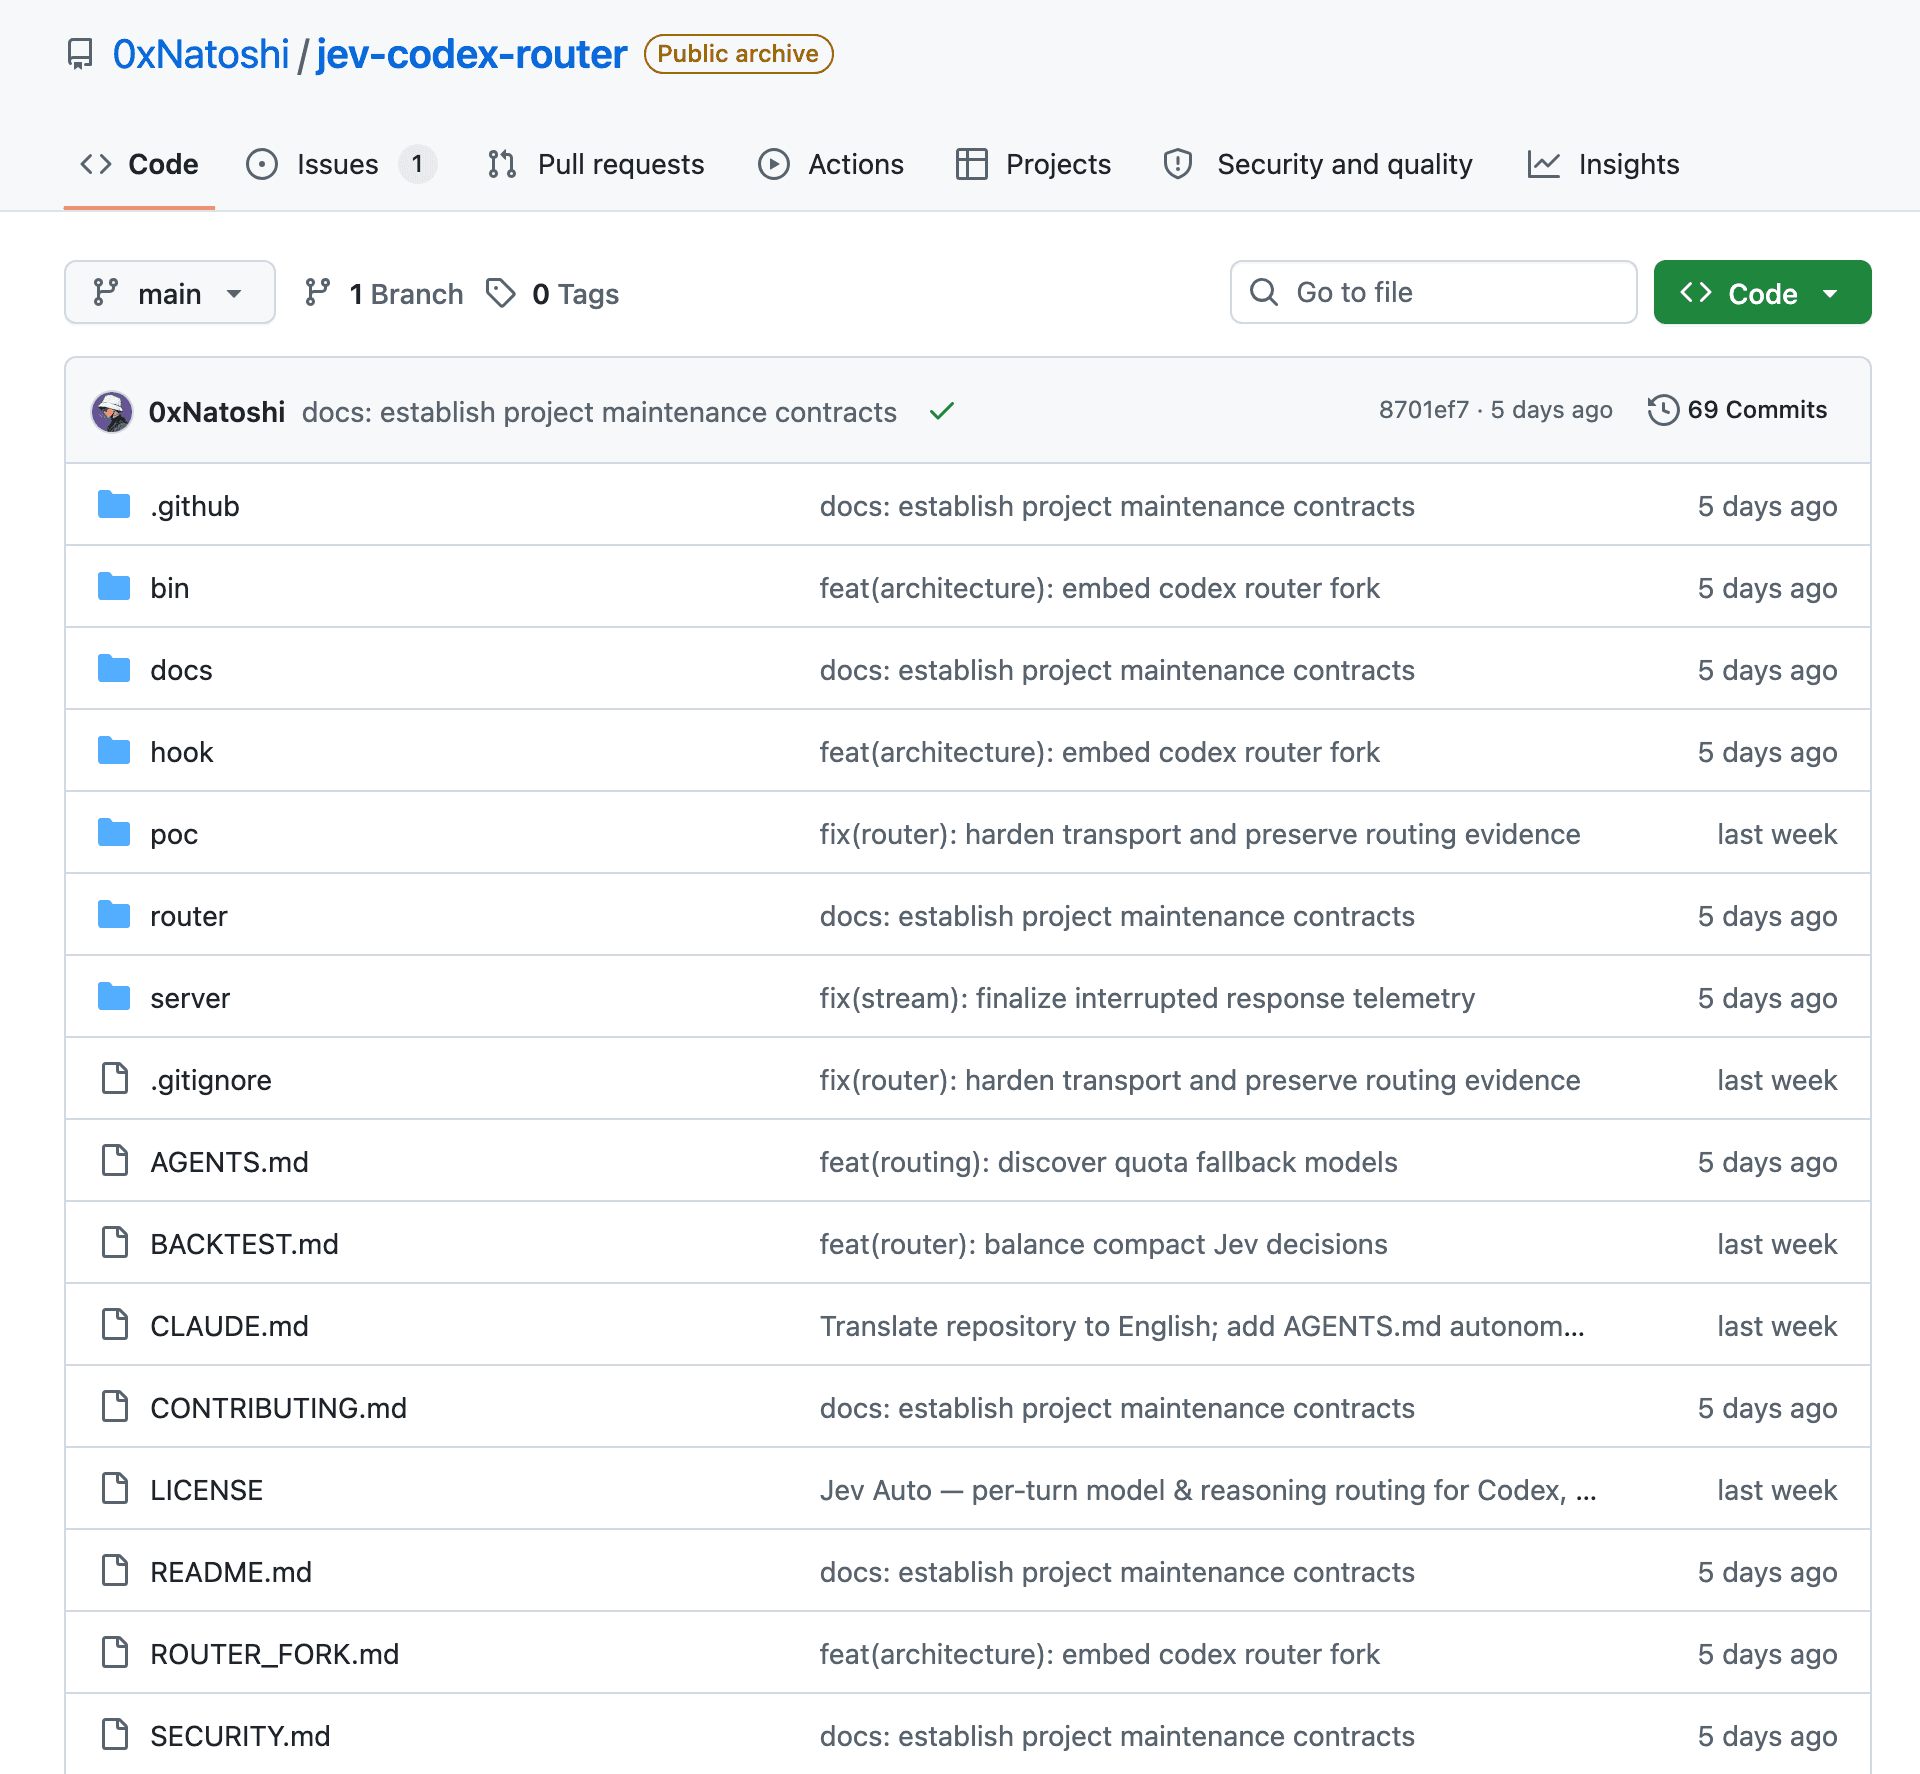
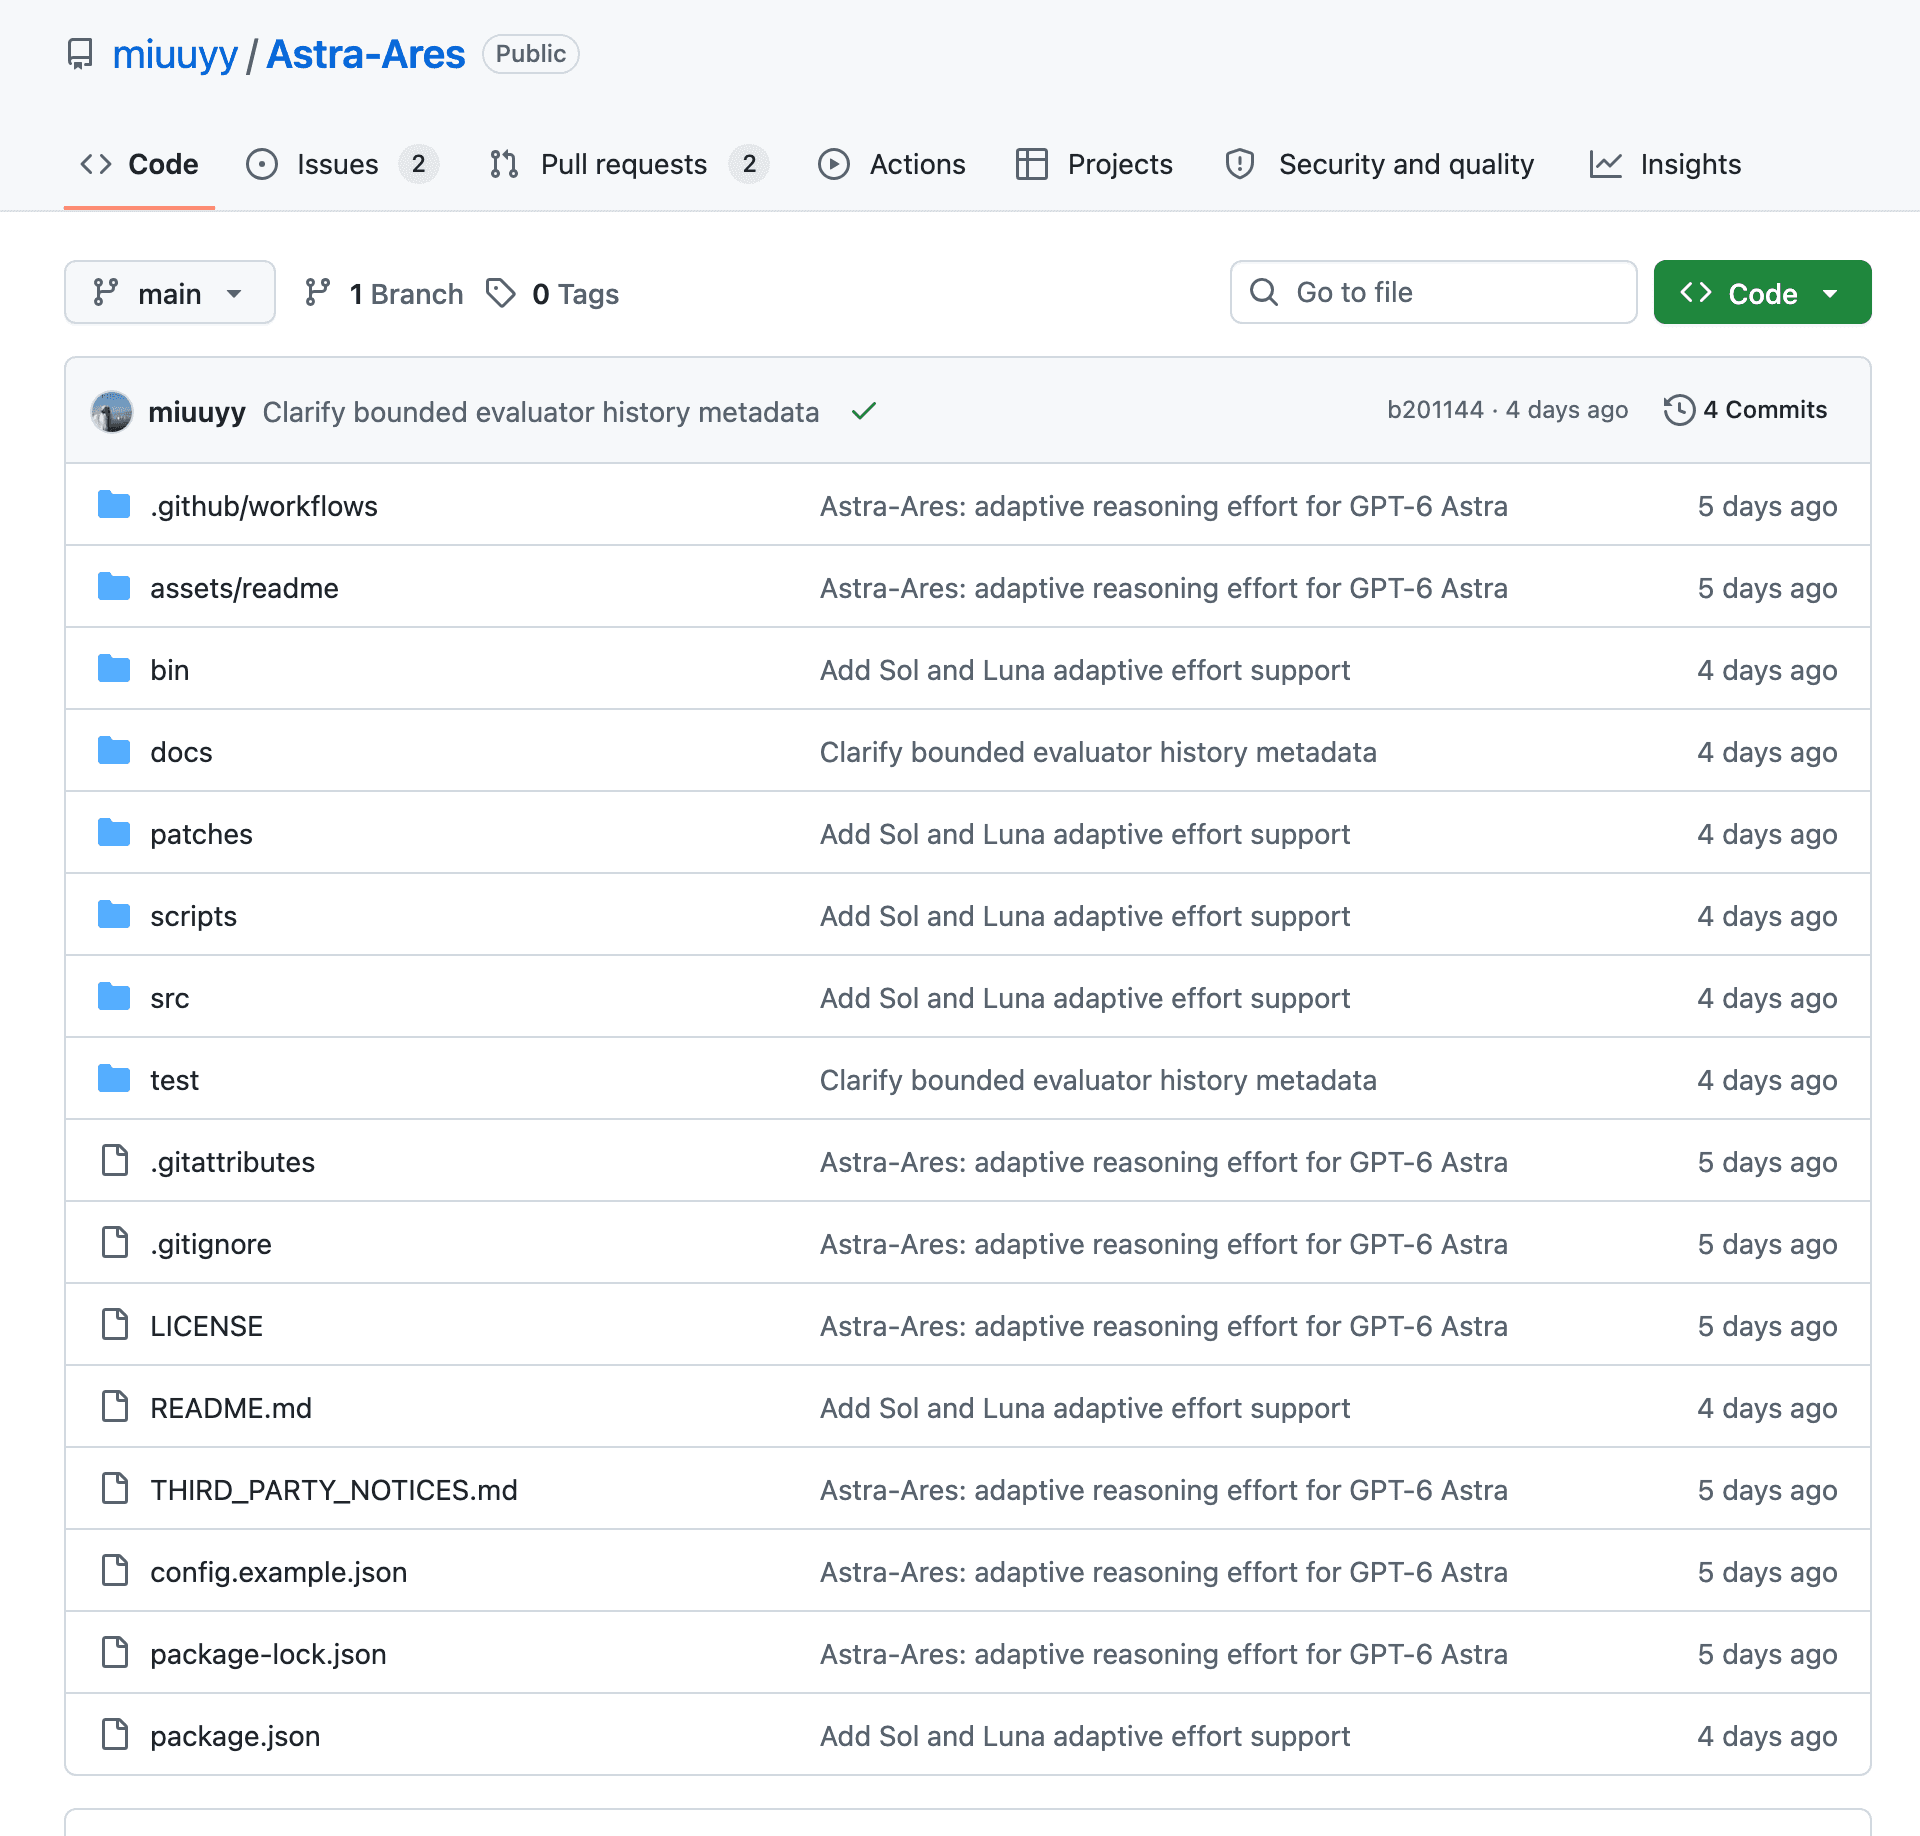
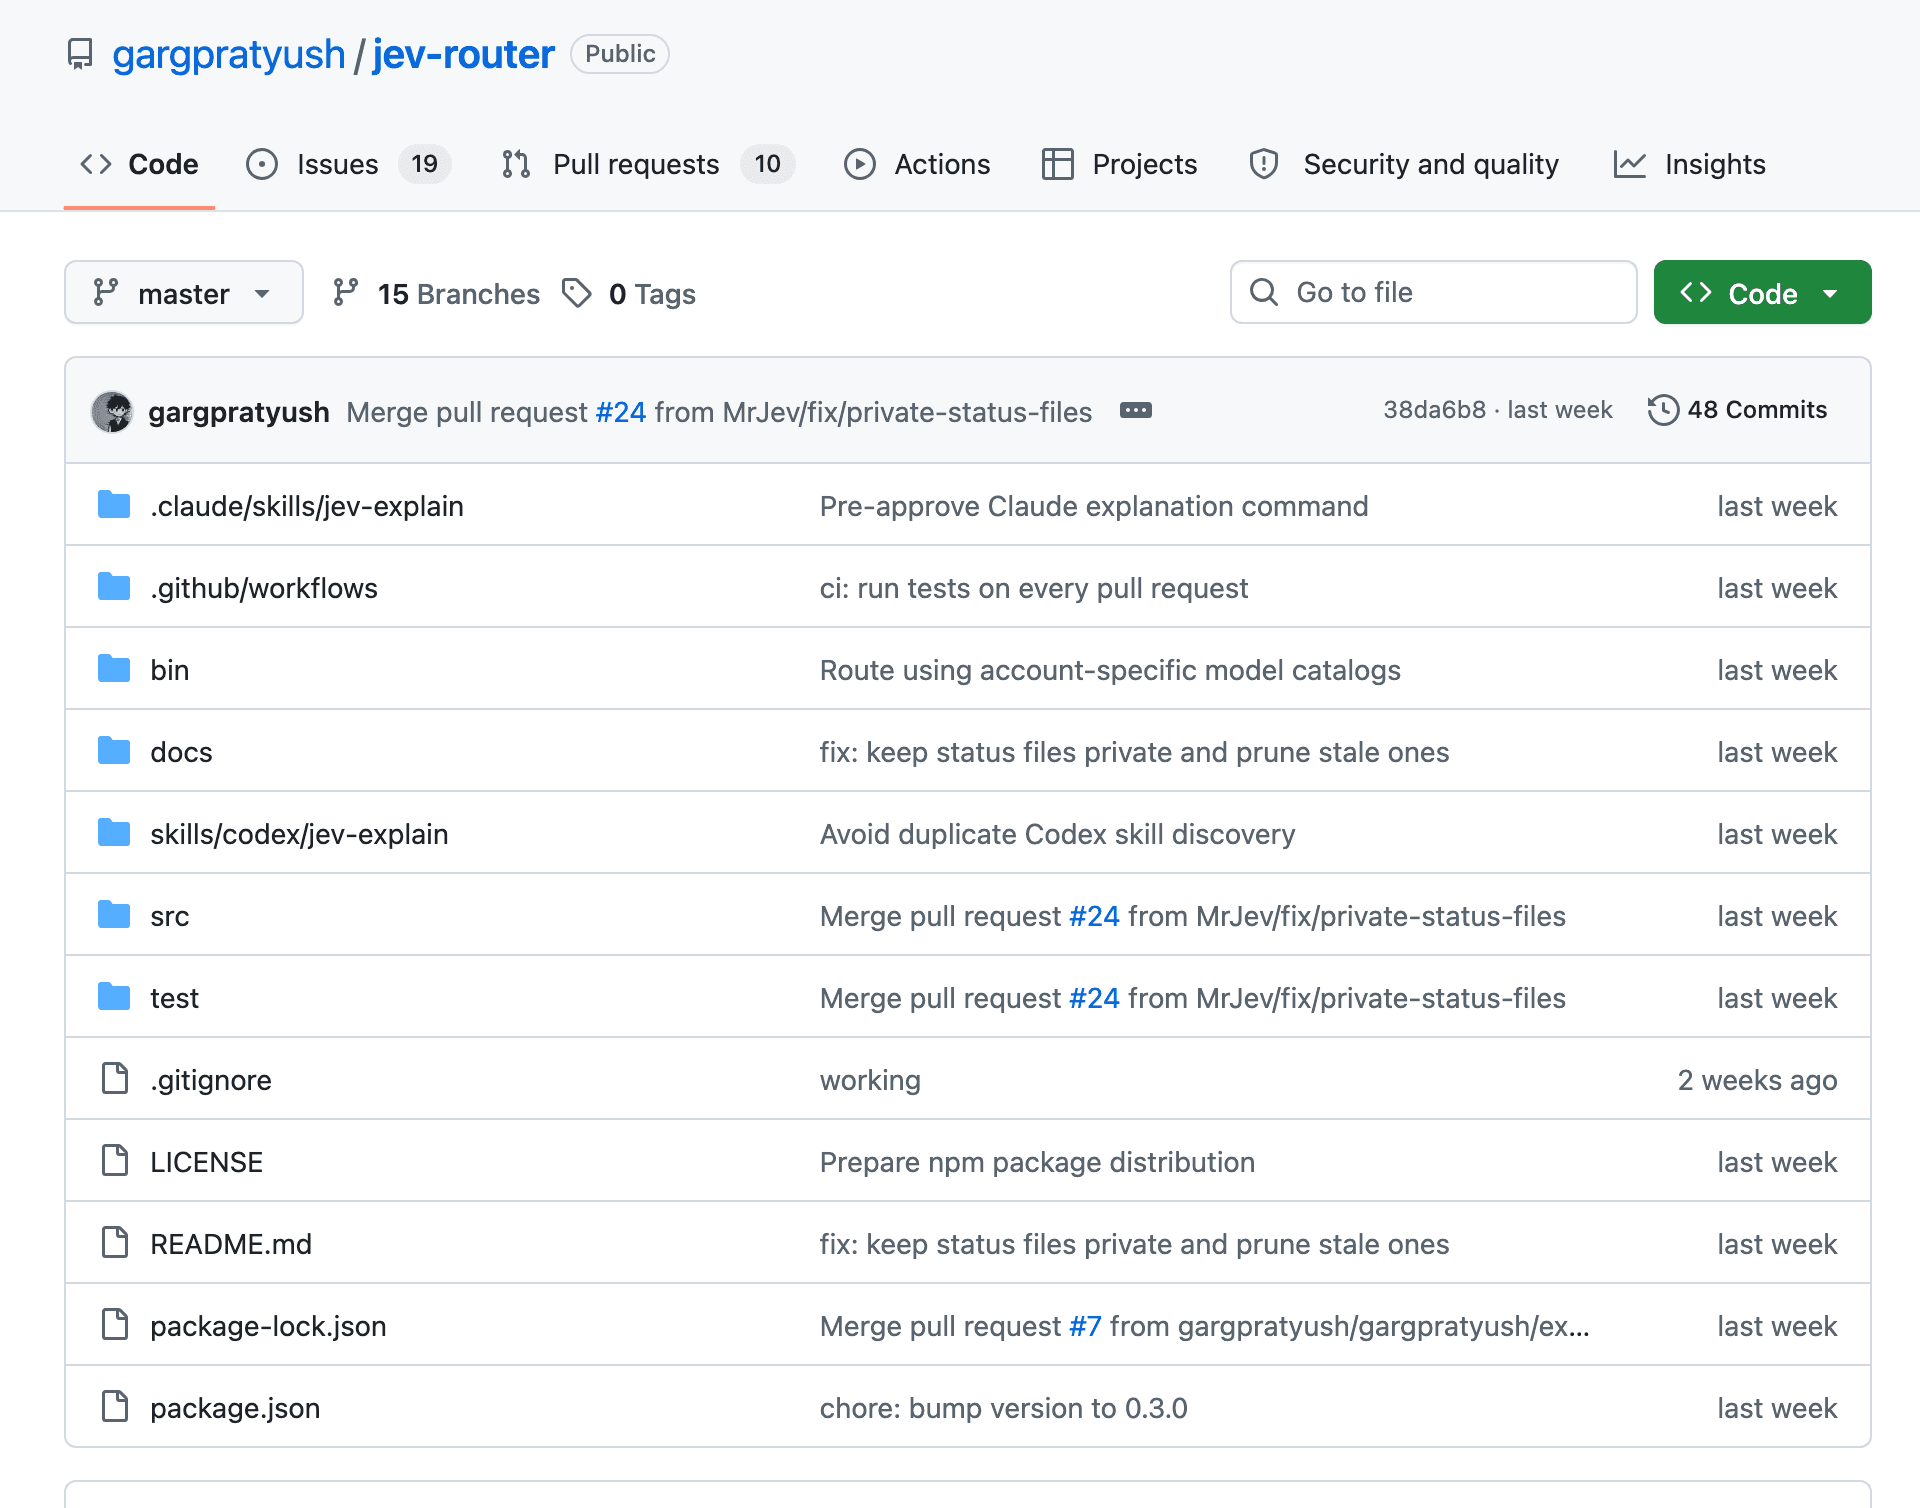
Sits in front of Codex and asks Jev, before each model call, how much capability the next step really needs. It then picks the model and the thinking effort to match.
The author's own replay of 237 past turns suggests about 60 percent less usage than always running the top model, and the repository is clear that this is a simulation, not a measured saving.
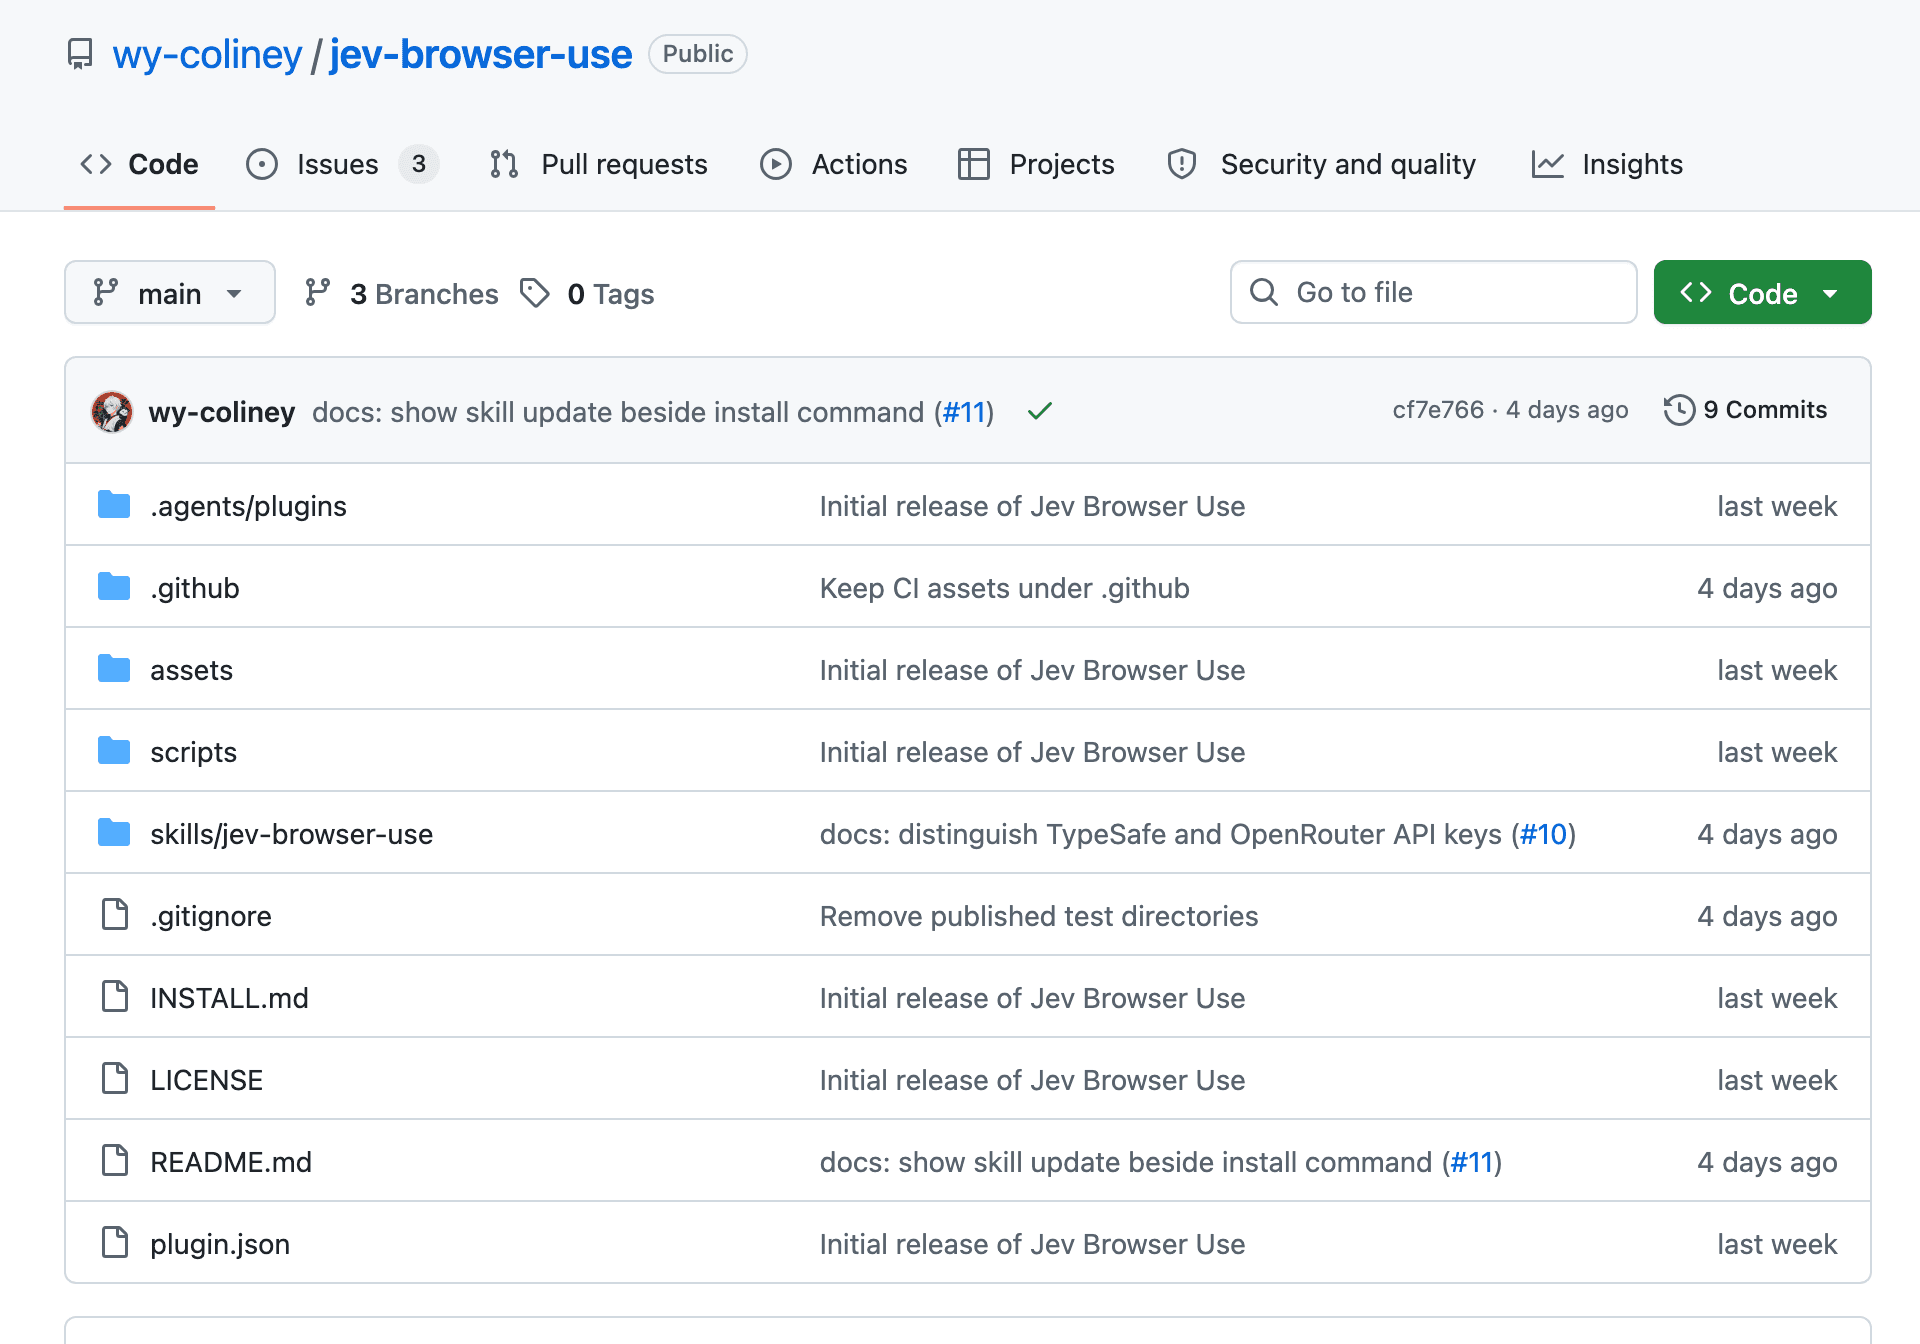
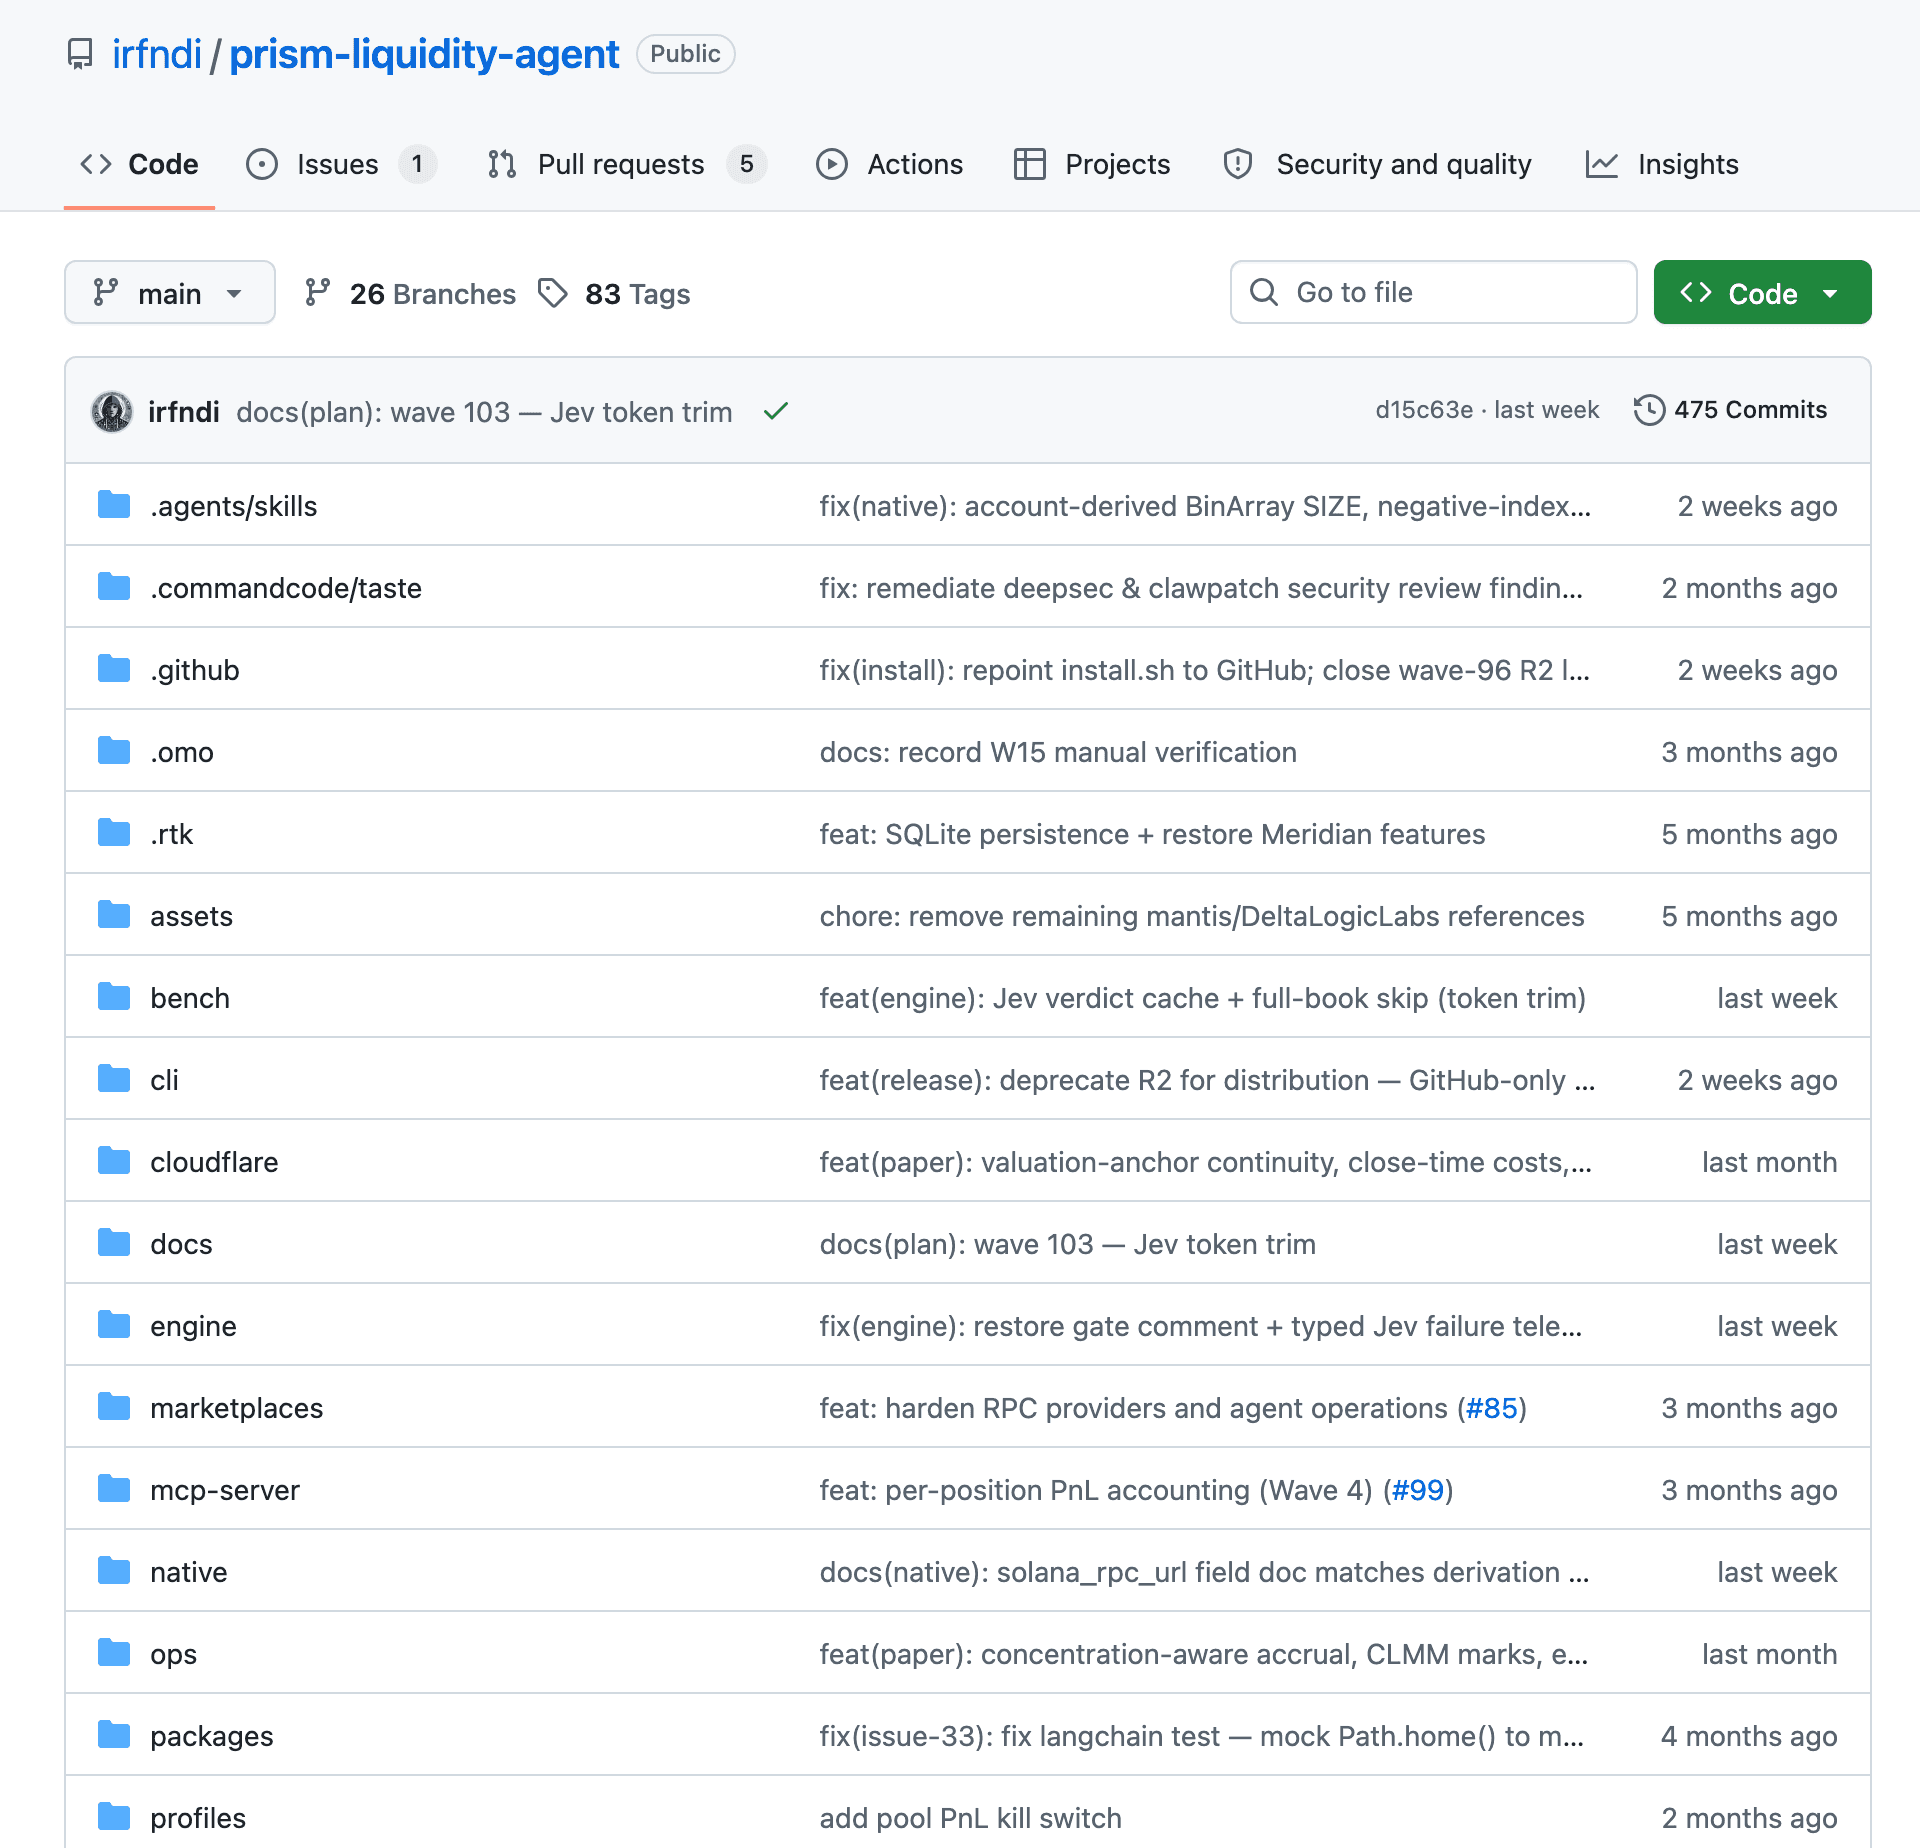
Includes an installer and a guide written for handing the setup to an AI agent.
What you get
- Full source code, MIT licensed
- The Codex Router fork it builds on
- Install script, backtest notes and docs
 Jev
 JavaScript
 Codex
 Rust

 Node.js
 Claude Code


 Python
 OpenCode

 TypeScript

 Bun
