
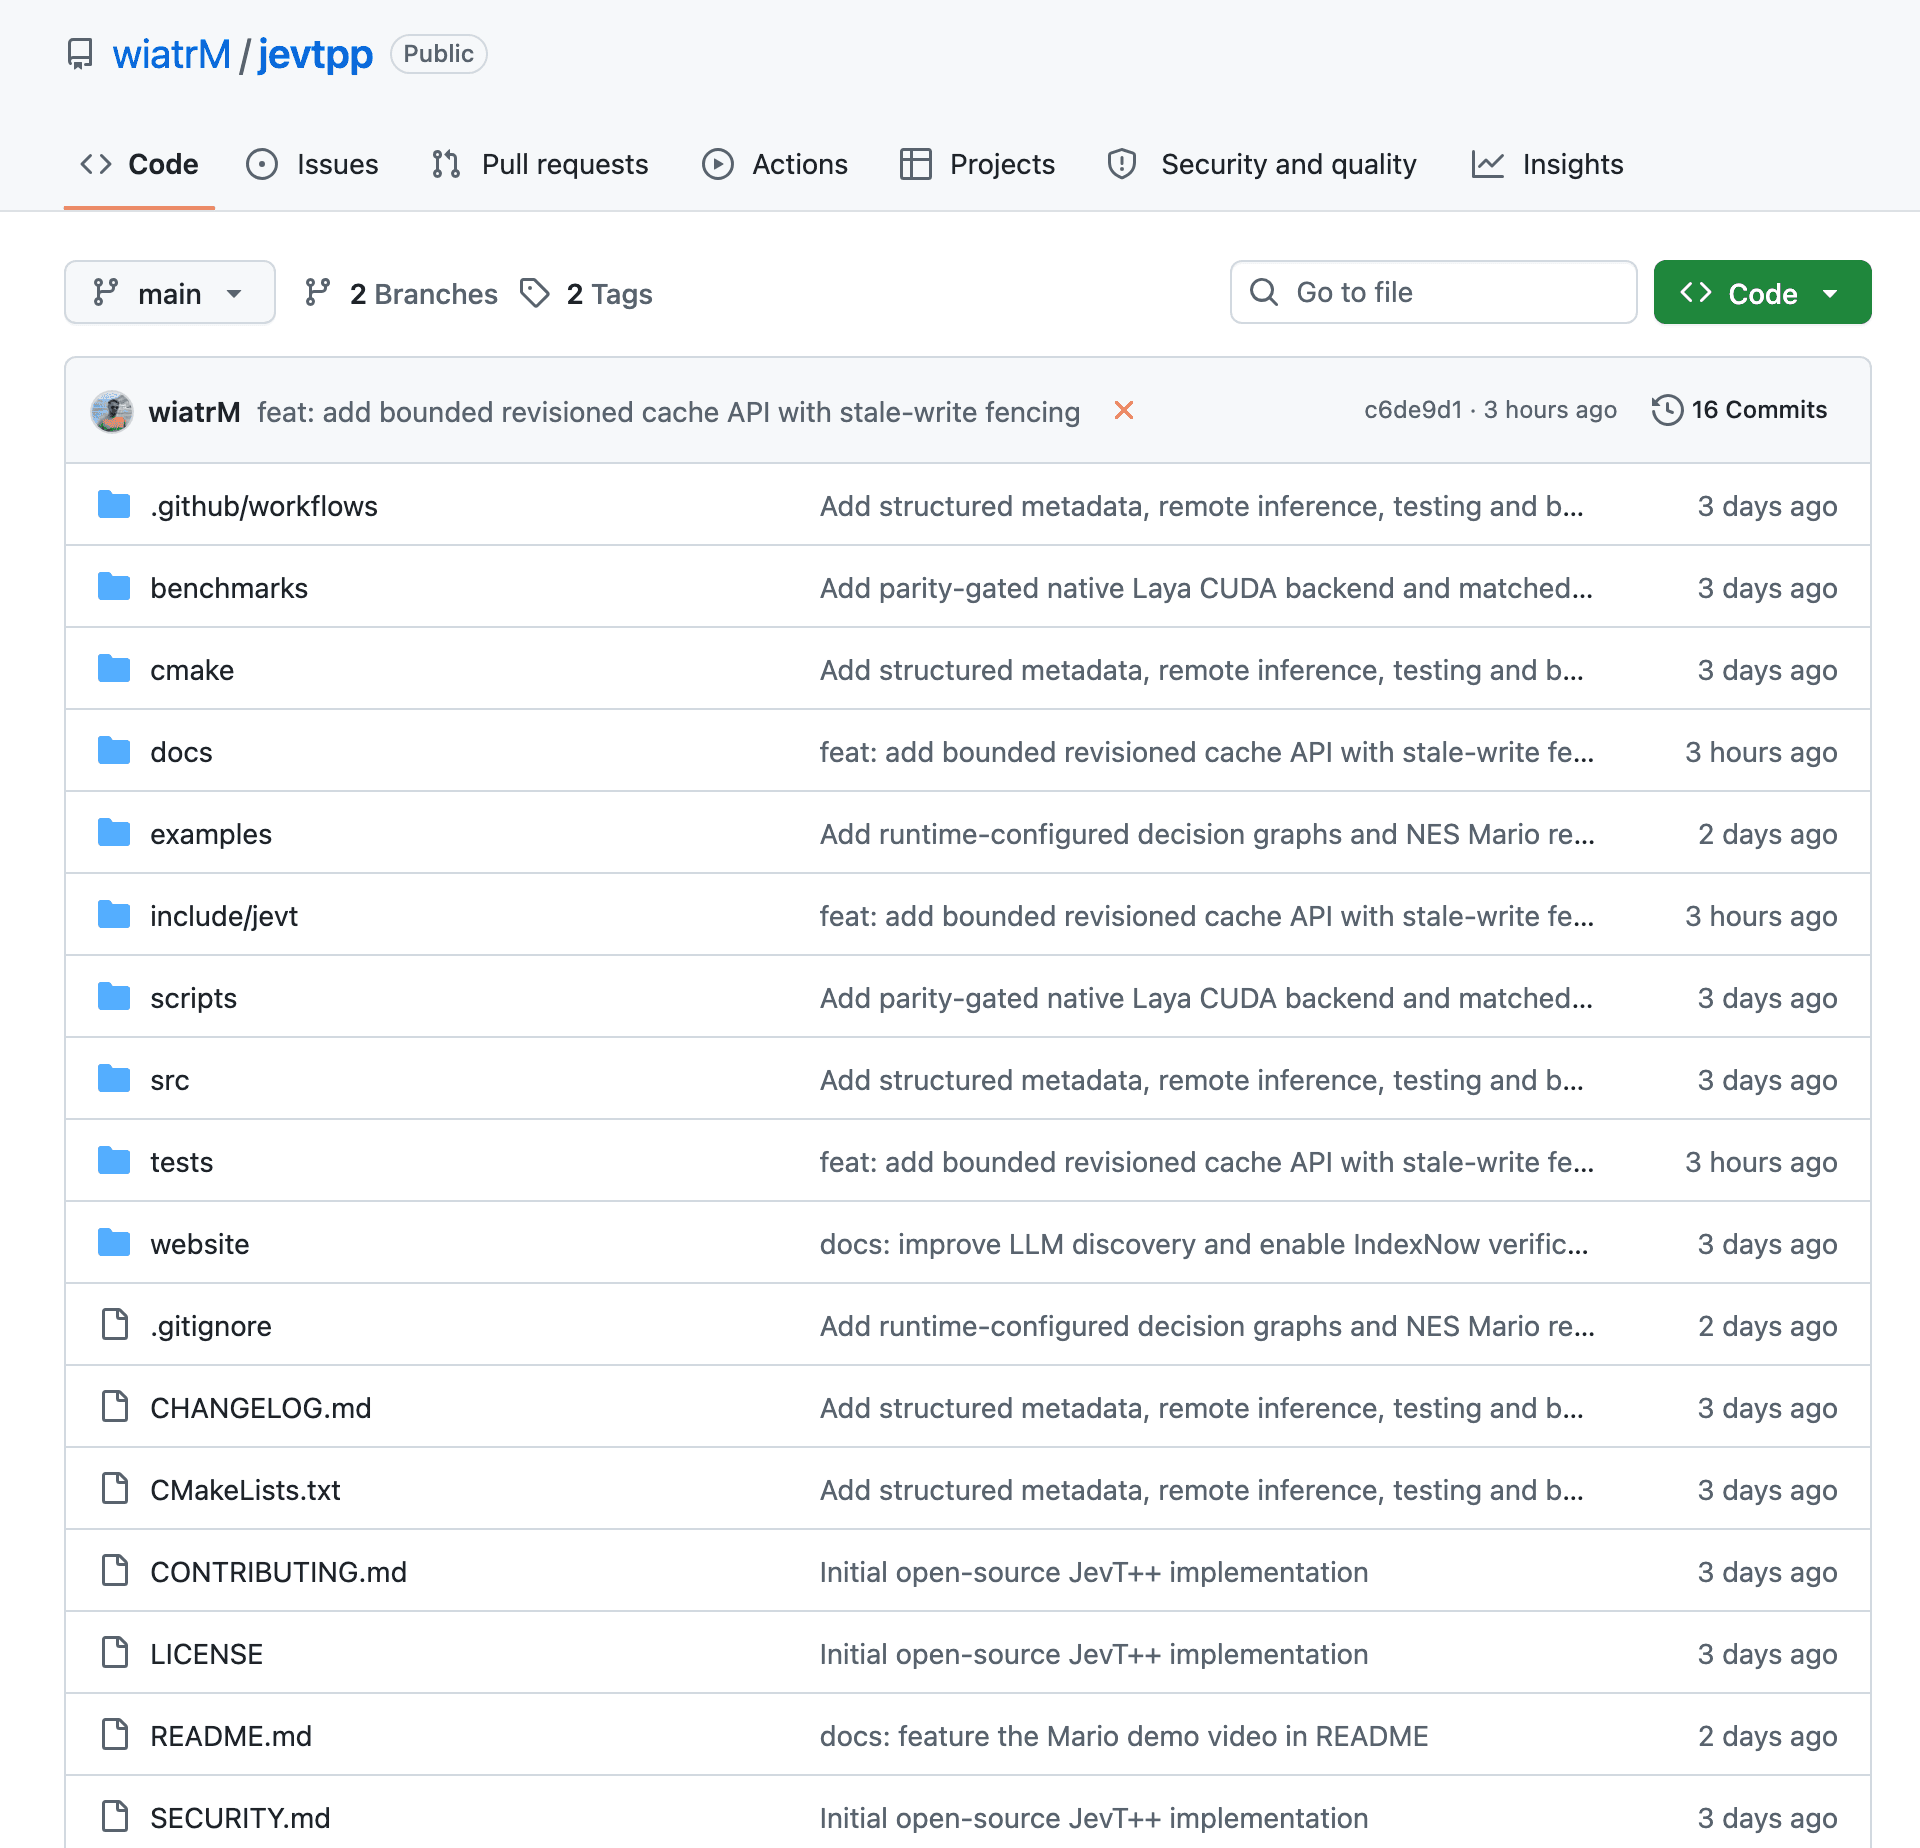
JevT++ lets C++ code ask a model a typed question, an enum, a yes/no, or a score, and get back an inspectable answer: full distributions, P(true), fractional scores and confidence, not a string to parse.
It runs inference in-process through ONNX Runtime or native ggml, or against a hosted backend through the same typed API, and ships with latency percentiles, JSON/Prometheus metrics and an optional loopback dashboard.
The builder's demo has a local model on CUDA rank candidate plans while JevT++ validates and executes them with guards and fallback control, controlling a Mario NES emulator through a Python bridge as a working proof of the integration.
What you get
- Full C++20 source code under the MIT license
- The Laya/ONNX and native CUDA backends, plus the runnable Mario demo
 Jev
 TypeScript
 Node.js

 Go

 Scala

 Python
 vLLM

 Claude Code

 Hono
